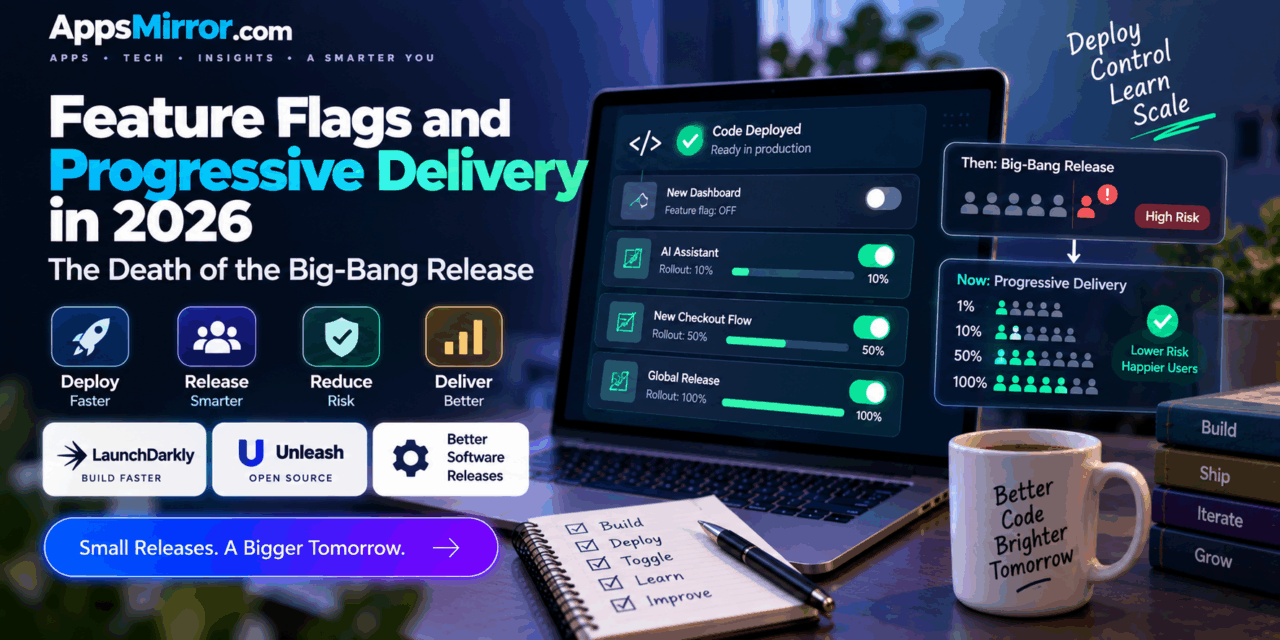
For most of software’s history, deploying code and releasing a feature to users were treated as the same event, a single big-bang moment where a new version shipped to everyone simultaneously, with all the risk that implies if something goes wrong. Feature flags decouple these two events entirely, letting a team deploy code to production while controlling exactly who actually sees a given feature through configuration rather than a code change, and progressive delivery builds on that foundation to roll features out gradually, to 1 percent of users, then 10, then everyone, rather than flipping a switch for the entire user base at once. By 2026, this pattern has moved from an advanced practice at a handful of large tech companies to genuinely mainstream tooling. Here’s an honest look at where feature flags and progressive delivery actually stand this year.
What Feature Flags Actually Solve
The core value proposition is genuinely simple and well-proven: decoupling deployment from release means a team can ship code to production continuously, multiple times a day if needed, without that code actually being visible or active for any real user until a flag is deliberately turned on. This eliminates the classic all-or-nothing release risk, since a problematic feature can be instantly disabled by flipping a flag rather than requiring an emergency rollback and redeployment, which used to take considerably longer and carried its own risk of introducing new problems during a rushed fix. Platforms like LaunchDarkly and the open-source Unleash have matured this pattern into genuinely robust, production-ready infrastructure, handling everything from simple on-off toggles to sophisticated percentage-based rollouts and user-targeting rules.
Progressive Delivery Beyond Simple On-Off Flags
Progressive delivery extends the basic feature flag concept into genuinely staged rollouts, releasing a new feature to a small percentage of users first, monitoring real production metrics for problems, and gradually expanding exposure only once the initial rollout demonstrates it’s actually safe. This pattern has become considerably more sophisticated in 2026, with tools now supporting automated rollback triggers that detect a spike in error rates or a drop in a key business metric and automatically halt or reverse a rollout without requiring a human to notice and intervene manually. Canary releases, where a new version runs alongside the old one for a small subset of traffic before a full cutover, and blue-green deployments, which maintain two complete production environments to enable instant, zero-downtime switching, have both become genuinely standard practice at companies serious about release safety rather than remaining exotic, rarely used techniques.
The Real Overhead This Introduces
The most consistently cited cost is genuine code complexity: a codebase riddled with feature flag conditionals that never get cleaned up after a feature fully launches becomes genuinely harder to read and reason about, with old, dead flag logic quietly accumulating as technical debt if a team doesn’t maintain real discipline about removing flags once they’re no longer needed. Testing also becomes more complex, since a codebase with multiple active flags theoretically has an exponentially larger number of possible states to verify, though in practice most teams limit active flag combinations enough that this rarely becomes a genuine testing nightmare. Feature flag platforms themselves introduce a real, additional dependency and cost, and teams need genuine flag-lifecycle discipline, tracking which flags exist, why, and when they should be removed, or the tooling investment can end up creating as much mess as it prevents.
Should Your Team Actually Adopt This Now
For teams shipping to a genuinely large or diverse user base, where a bad release could cause meaningful damage before anyone notices, or where different user segments need different feature timing, feature flags and progressive delivery remain a legitimate, well-tooled, and increasingly standard investment in 2026. Smaller teams with a modest, homogeneous user base and infrequent releases may find the added tooling and flag-lifecycle discipline genuinely disproportionate to their actual release risk, since the core problem this pattern solves, catastrophic simultaneous exposure to a broken release, matters less at smaller scale where a quick rollback affects fewer people and less revenue. As with most infrastructure investments covered this year, the right question isn’t whether feature flags are good practice, they clearly are for the right context, but whether a specific team’s release risk and user base genuinely justify the added tooling and discipline the pattern demands.
Looking at where feature flags and progressive delivery actually stand in 2026, the honest assessment is that the big-bang release genuinely has become the exception rather than the default at any team seriously concerned about release safety, a real, substantive shift from where the industry stood even five years ago. The teams getting genuine value from this pattern are treating flag-lifecycle management as seriously as the initial adoption itself, actively removing dead flags rather than letting them accumulate indefinitely as silent technical debt. As feature flag platforms continue maturing their automated rollback and monitoring integration, expect progressive delivery to keep becoming the practical default for any team shipping to a meaningful user base, even as smaller teams with lower release risk reasonably continue shipping the simpler way.
Conclusion
Feature flags and progressive delivery have made genuine, substantive progress toward killing the big-bang release in 2026, and for teams shipping to a real, meaningful user base, this pattern has moved decisively from advanced practice to mainstream expectation. It isn’t universally necessary for every team, and the flag-lifecycle discipline it demands is real, but for organizations where a bad release genuinely carries real risk, this year’s mature tooling has made progressive delivery a legitimate default rather than an aspirational best practice reserved for the largest tech companies.